Real-Time SAP to IBM watsonx.data Integration with Onibex OneConnect
Onibex Team
Last updated: September 2026
What is real-time SAP to IBM watsonx.data integration?
Real-time SAP to IBM watsonx.data integration is the continuous delivery of SAP ECC and SAP S/4HANA business events to Apache Iceberg tables queryable through IBM watsonx.data, without polling, without ABAP development, and without custom ETL. Onibex OneConnect handles capture, serialization, schema registration, and Iceberg writes automatically through a Presto sink connector, from the moment a record changes in SAP.
The 4 key points:
- SAP business events — ABAP RESTful Application Programming (RAP), Business Object Repository (BOR), Business Transaction Events (BTE), and Post Processing Framework (PPF) — fire at the application layer the instant a record is created, modified, or deleted, not on a fixed polling schedule
- The Smart Gateway serializes each record into Avro format, registers the schema automatically in the Confluent Schema Registry, and creates the Kafka topic with no manual configuration
- The Onibex Premium Presto Sink Connector reads each topic and writes SAP records directly into Apache Iceberg tables in Amazon S3, using the schema already registered, with no separate mapping layer
- The SAP Data Modeler exposes VBAK, VBAP, custom Z-tables, and Core Data Services (CDS) Views through a visual drag-and-drop interface, with no ABAP code at any step
How does OneConnect model SAP tables for IBM watsonx.data?
A sales order in SAP ECC and SAP S/4HANA lives across two tables: VBAK (the header: customer, document date, sales organization) and VBAP (the line items: material, quantity, net value). Modeling that relationship for IBM watsonx.data starts inside the Onibex SAP Data Modeler, the same tool described in SAP to Kafka integration with OneConnect.
The SAP Data Modeler provides a visual interface where VBAK and VBAP are added, connected by dragging and dropping, and field aliases are assigned. NETWR becomes "net value." KUNNR becomes "customer." No SQL, no ABAP function modules, and no developer dependency for every schema change.
The output is a data product: a complete business package with its tables, relationships, and aliases resolved. Once built, it is reusable for any future destination (Databricks, Snowflake, a dashboard, IBM watsonx.data) without rebuilding the SAP logic from scratch.
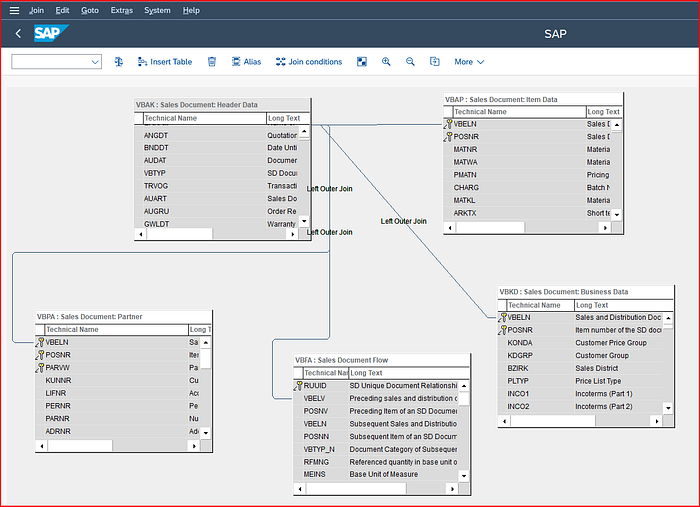
Data product design for Sales Order in the SAP Data Modeler
No special configuration is needed on the SAP side for the data to land cleanly in IBM watsonx.data. The SAP Data Modeler produces a structured, destination-agnostic data product. The same model that feeds IBM watsonx.data today can feed Databricks or Snowflake tomorrow without touching the SAP configuration again.
The SAP Data Modeler also supports custom Z-tables and CDS Views directly, so custom fields and existing CDS Views built for internal reporting are pulled in without re-implementing that logic inside the tool.
How do SAP business events guarantee real-time delivery?
The SAP Data Modeler resolves the structure of the data. Business events resolve the timing.
Every time a sales order is created, modified, or deleted in SAP, an application-layer business event tied to that entity fires. On SAP ECC and SAP S/4HANA installations up to 2022, this runs on BOR Events. On SAP S/4HANA 2023 and later, it runs on RAP Events. The result is the same in both cases: the modified record travels outbound over an HTTP Remote Function Call (RFC) destination of Type G to the Smart Gateway the instant the change is committed, without waiting for a scheduled extraction job.
This is the property that ensures data later consumed by IBM watsonx.data, a dashboard, or an AI agent is current by design. The change is already in transit from the moment it is committed in SAP.
The same mechanism governs deletes. A delete in SAP triggers the same application-layer business event as a create or update. Delete propagation is part of the design at the source, not a step added afterward in the pipeline.
What does the Smart Gateway do between SAP and Kafka?
Once VBAK and VBAP are modeled and connected to their business events, the Smart Gateway takes over. It performs four steps automatically:
- Receives the delta from SAP. The modified record, whether an insert, update, or delete, arrives at the Smart Gateway at the moment the business event fires, pushed over the RFC Type G destination.
- Serializes the record into Avro format. Avro enforces a defined type for every field and validates each record before writing. This prevents a field from arriving as a string in one record and null in the next, the kind of inconsistency that breaks a downstream pipeline without warning.
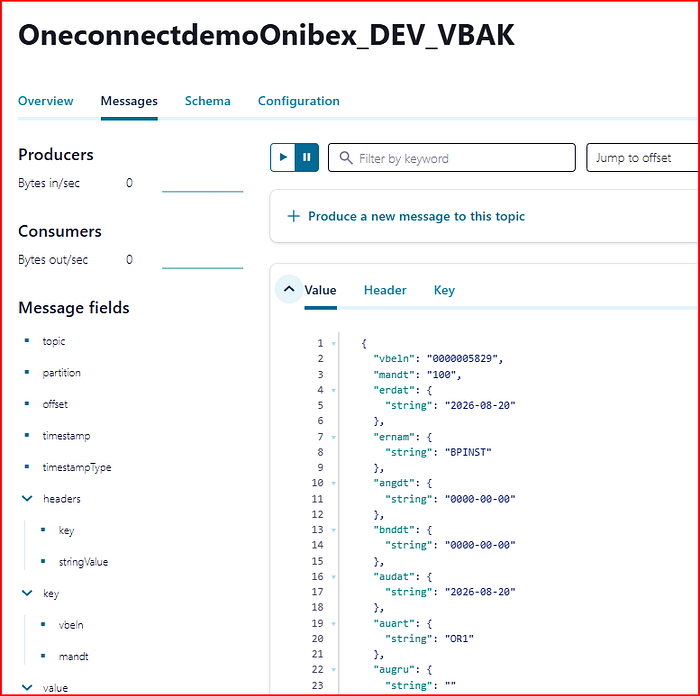
VBAK topic message serialized in Avro
- Registers the schema in the Confluent Schema Registry. The schema for each data product is generated automatically from the metadata the SAP Data Modeler already holds about VBAK and VBAP. No manual schema authoring is required.
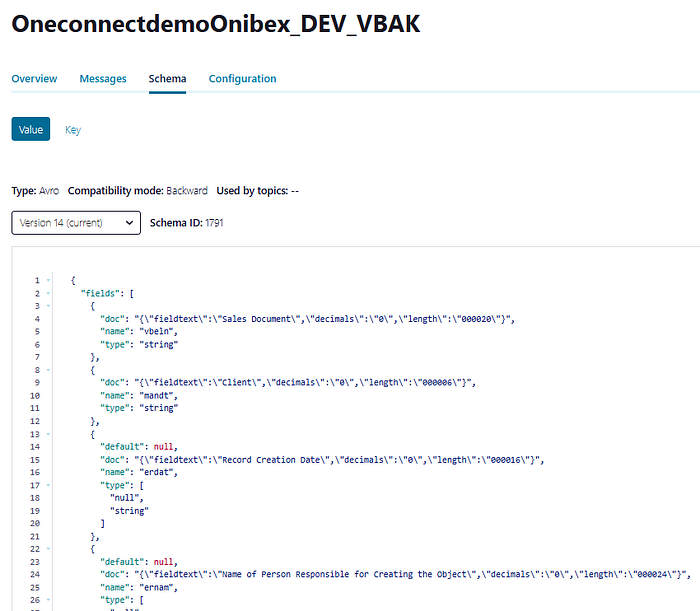
Avro schema registry for the VBAK topic
- Creates the Kafka topic automatically. The topic name is based on the entity, and the topic is ready from the moment the data product is activated on Apache Kafka.
From that point forward, every change to the sales order writes a new Avro record to the topic, with the schema enforced by the registry.
How does the Onibex Premium Presto connector write to IBM watsonx.data?
Instead of a Databricks connector, the sales order topic is picked up by the Onibex Premium Presto Sink Connector, configured directly from the Smart Gateway alongside the same catalog of pre-built destinations for Snowflake, Databricks, HANA, SQL Server, PostgreSQL, DB2, BigQuery, Amazon S3, Google Cloud Storage, and Microsoft Fabric.
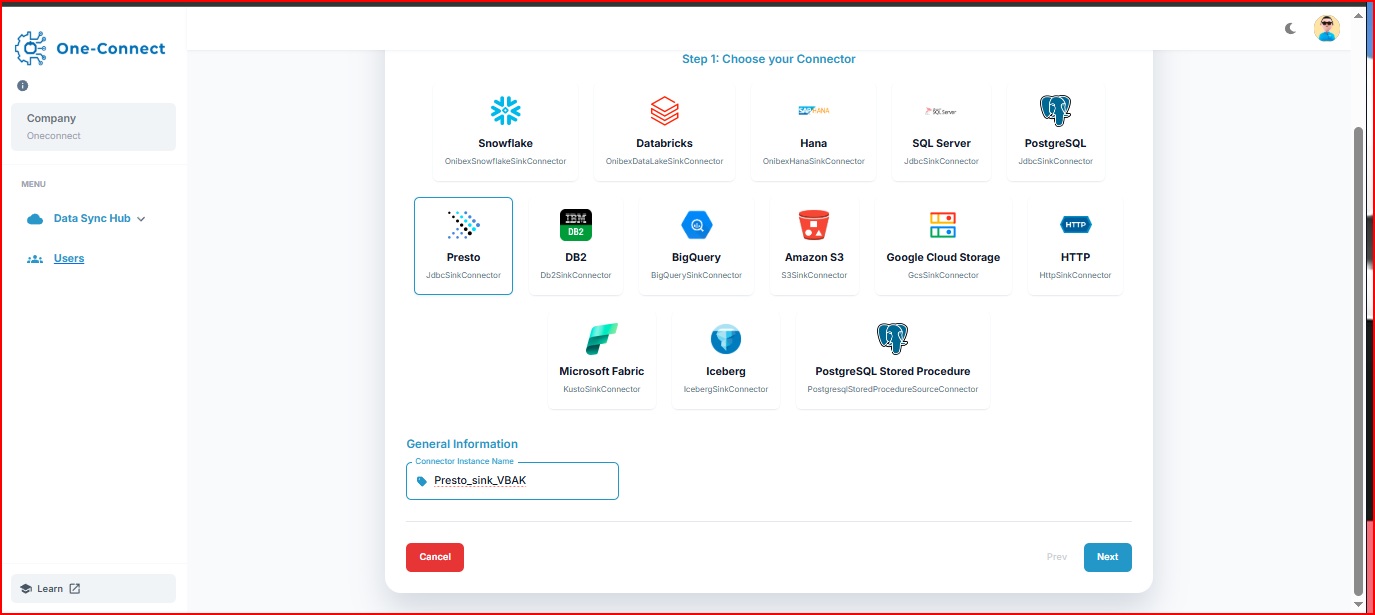
Selecting the Presto connector in the Smart Gateway's connector catalog
Configuring it follows the same short wizard used for every other destination: a JDBC connection URL pointing at the Presto engine, the connection user, the Onibex license, and either an explicit topic name or a topics regex. Nothing about the SAP side changes because SAP communicates only with Kafka, not with Presto directly.
From there, Presto receives the Avro records from Kafka and writes them into an Apache Iceberg table, using the same schema the Smart Gateway already registered in the Schema Registry. Presto does not need to infer the structure of the sales order; it reads the schema directly from the registry.
| Step | What happens | Configured by |
|---|---|---|
| SAP Data Modeler | VBAK and VBAP joined, business aliases assigned | Analyst or architect, no ABAP |
| Business event | Change captured at application layer, sent over RFC Type G | Automatic on every commit |
| Smart Gateway | Avro serialization, schema registration, Kafka topic creation | Automatic |
| Presto connector | Topic consumed, Iceberg table written in S3 | Configured from Smart Gateway UI |
Where does SAP data land inside IBM watsonx.data?
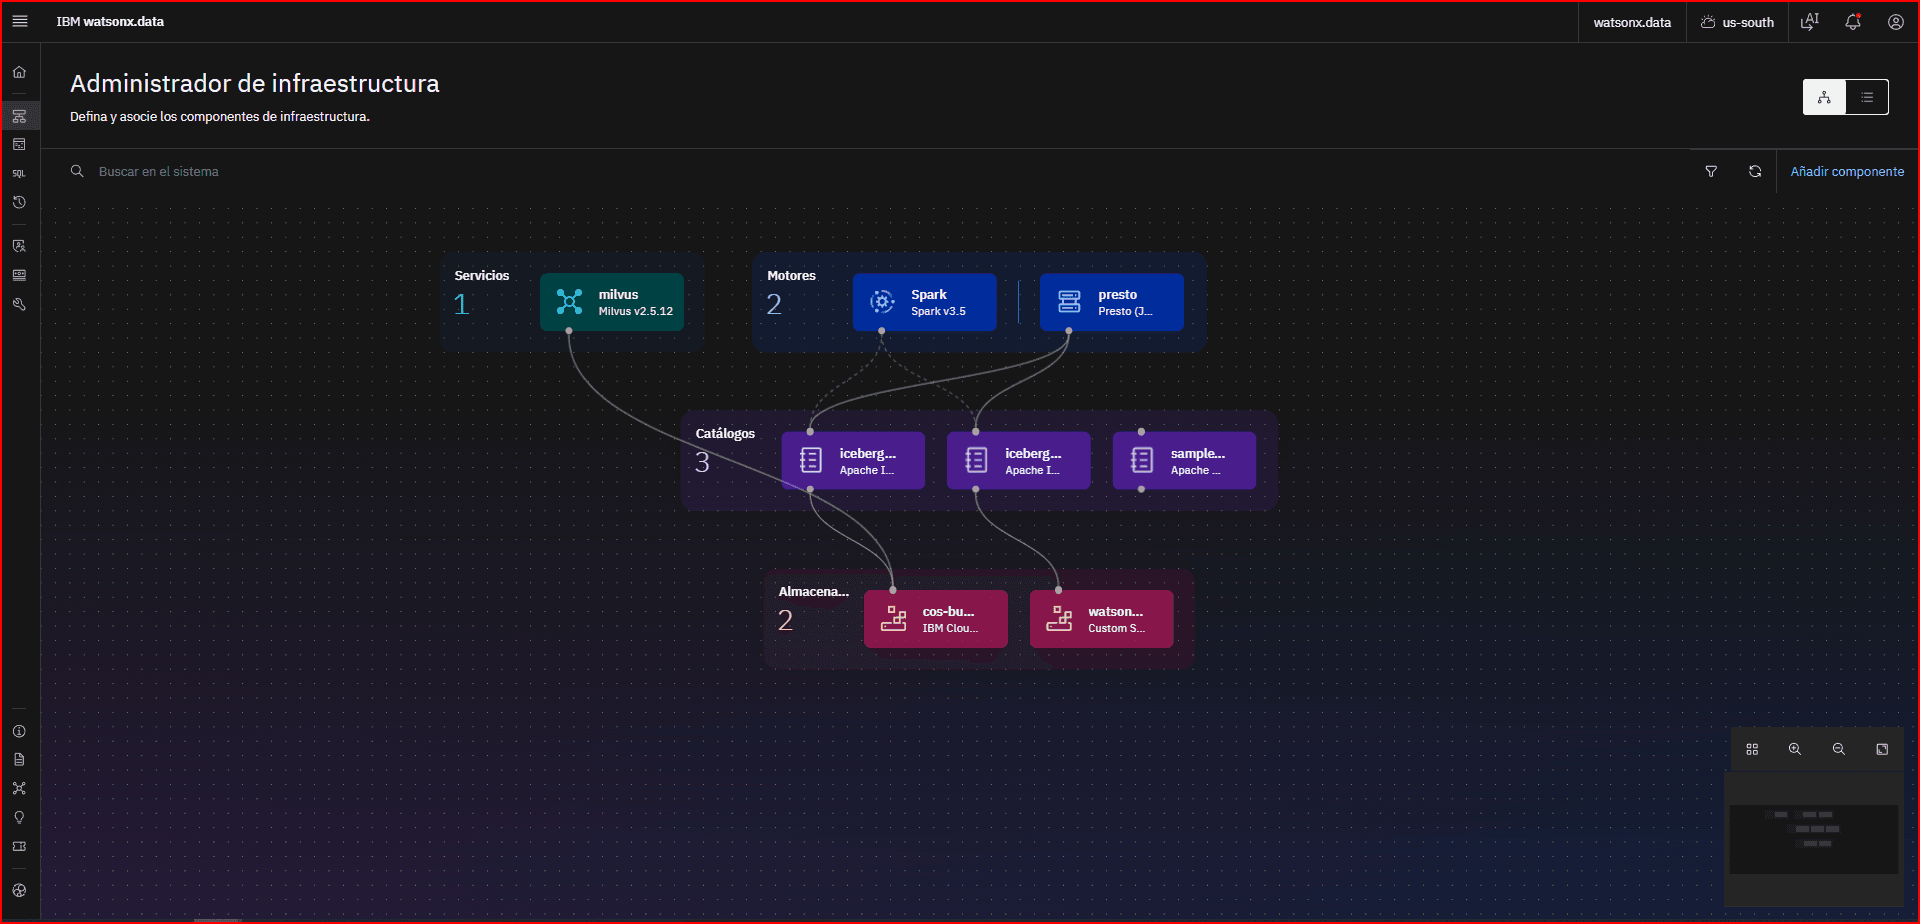
IBM watsonx.data is the platform where this all comes together. Behind the scenes, it runs on Presto and Spark engines that read and write against Iceberg catalogs backed by object storage in Amazon S3.
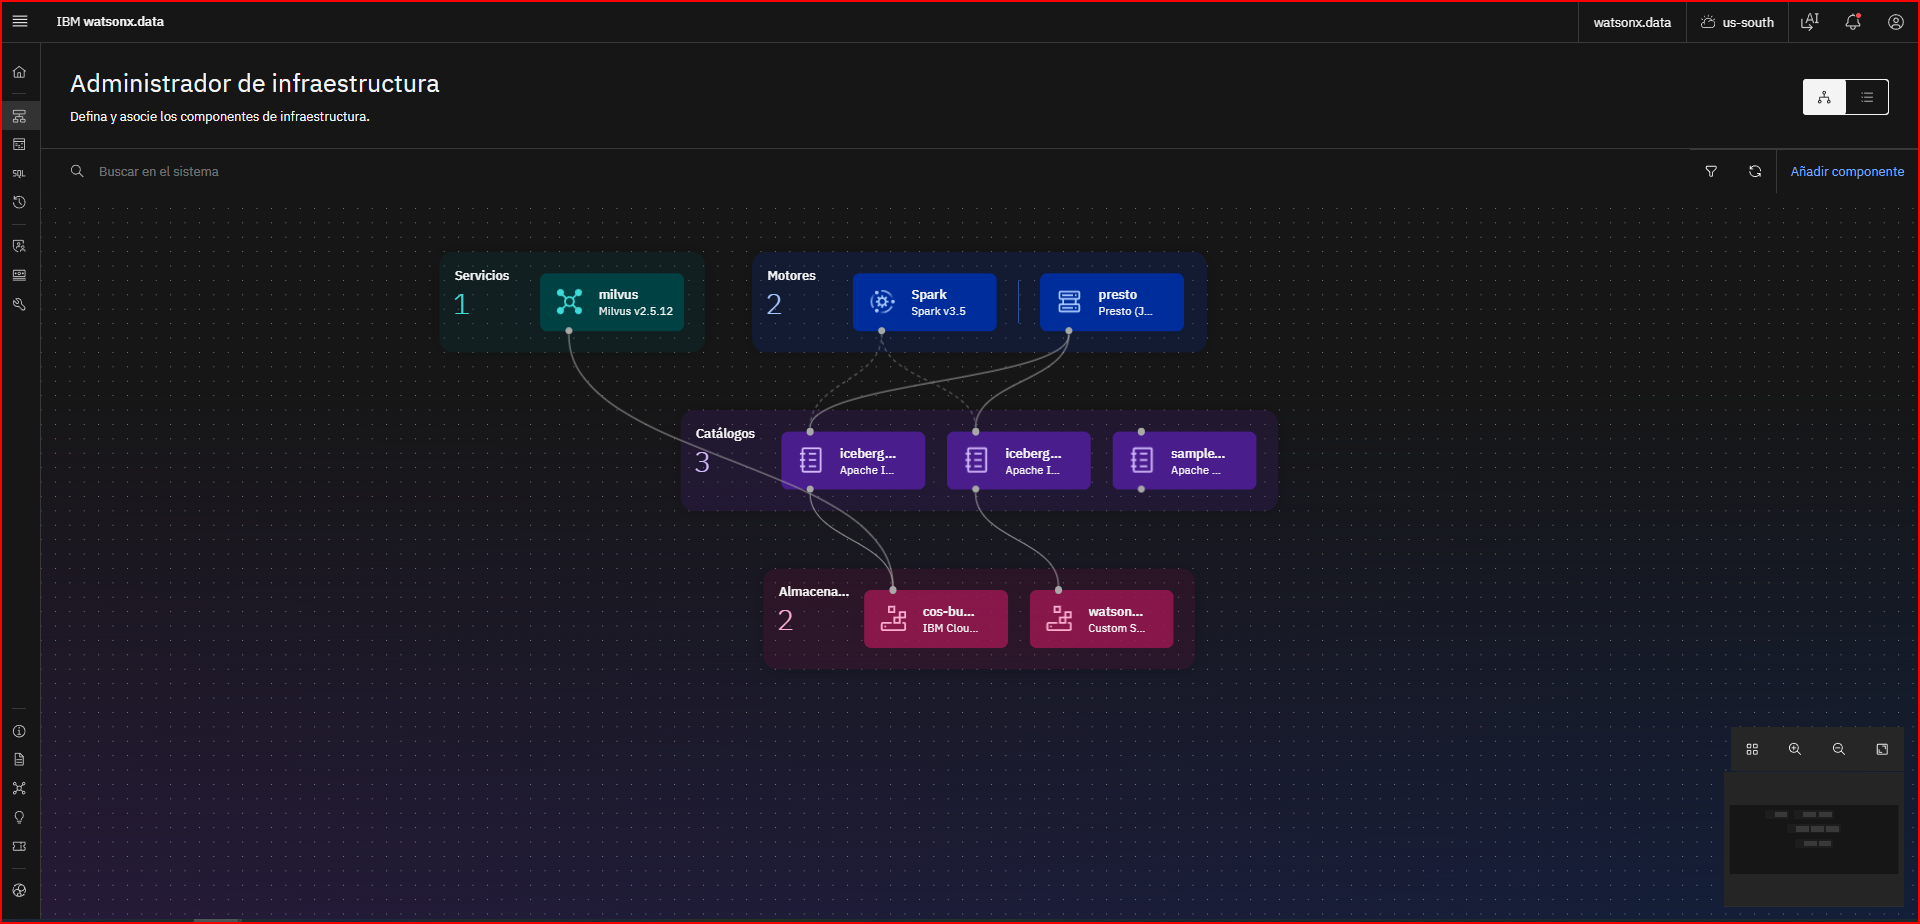
IBM watsonx.data infrastructure: Presto and Spark engines, Iceberg catalogs, and S3-backed storage
The Presto connector writes the sales order records into an Apache Iceberg table inside the "bronze" schema of the Iceberg catalog. Physically, that table is a set of Iceberg metadata and data files sitting in an S3 bucket, organized in a folder per SAP table.
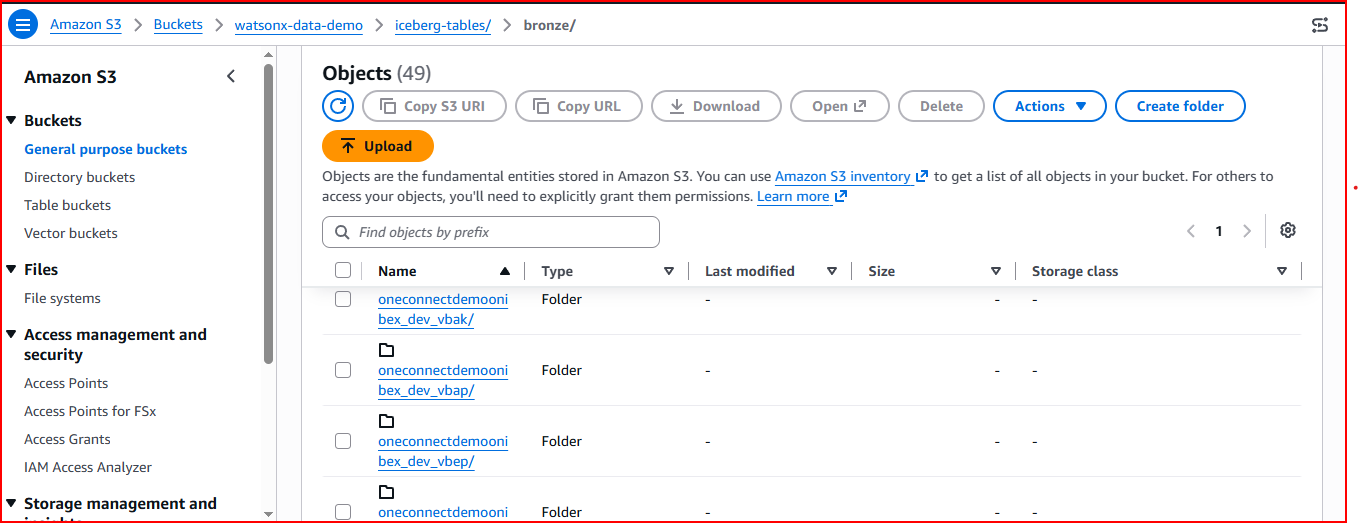
The resulting Iceberg tables stored in the S3 bucket
From IBM watsonx.data's own data explorer, that table is immediately queryable through the Presto engine, with every field already typed and named exactly as the SAP Data Modeler defined it: vbeln, mandt, erdat, ernam, auart, and the rest of the sales order header.
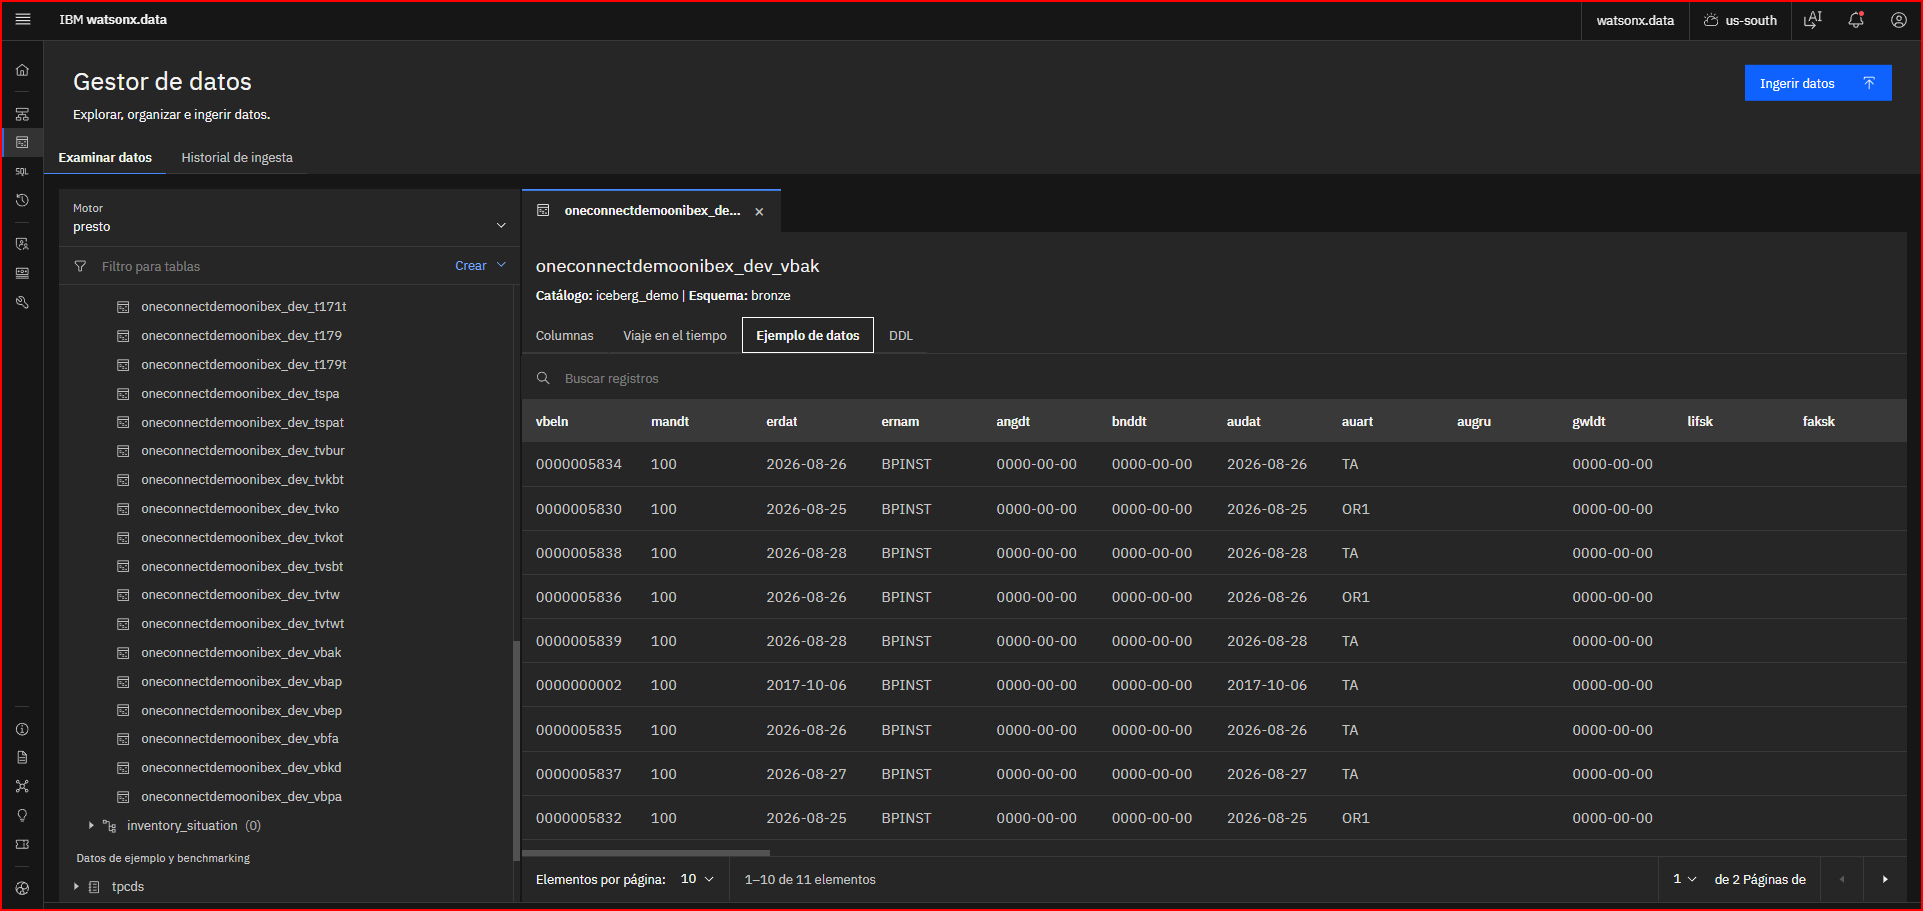
Browsing the VBAK Iceberg table from IBM watsonx.data's data explorer
Because Apache Iceberg is an open table format, those same files in Amazon S3 are not locked into IBM watsonx.data. Any engine with Iceberg support — Spark, Presto, or another lakehouse tool — can read the exact same tables without any data movement.
Frequently asked questions
Does real-time SAP to IBM watsonx.data integration require ABAP development?
No. The SAP Data Modeler provides a visual drag-and-drop interface for defining the data product, and the Smart Gateway automatically manages Avro schemas, Schema Registry entries, and Kafka topic creation. No ABAP function modules or custom extractors are written at any step of the OneConnect flow.
Why does the connector point at Presto instead of IBM watsonx.data directly?
Presto is the query engine IBM watsonx.data uses to read and write against its Iceberg catalogs. Pointing the Presto Sink Connector at Presto's JDBC endpoint is what lands the data as Iceberg tables that IBM watsonx.data can query, browse, and share with any other engine that reads Iceberg.
Is the resulting Iceberg table locked into IBM watsonx.data?
No. Apache Iceberg is an open table format. The same files in Amazon S3 can be read by Spark, Presto, or any other engine with Iceberg support, independently of IBM watsonx.data.
Does this only work with sales orders?
The sales order is the example in this post, but the same flow applies to any data product modeled in the SAP Data Modeler: billing documents, material masters, customers, vendors, and any Z-table or CDS View in the SAP installation.
What OneConnect does not do
OneConnect does not write to IBM watsonx.data directly. SAP business events travel to Kafka via the Smart Gateway, and the Presto Sink Connector handles the Iceberg write. IBM watsonx.data is the query layer, not the ingest target.
OneConnect does not access the SAP database layer. All capture happens through application-layer business events (RAP, BOR, BTE, PPF) pushed outbound over an HTTP RFC destination of Type G to the Smart Gateway. No direct database access is involved on the SAP side.
OneConnect does not support SAP S/4HANA Cloud Public Edition. The supported systems are SAP ECC, SAP S/4HANA, and SAP S/4HANA Cloud Private Edition.
OneConnect does not require a separate Kafka Connect deployment. The Presto Sink Connector is configured and managed from the Smart Gateway interface, with no additional infrastructure to operate.
About Onibex
Onibex builds real-time data streaming and agentic AI solutions for SAP environments. Onibex OneConnect captures business events from SAP ECC and SAP S/4HANA through application-layer mechanisms (RAP, BOR, BTE, PPF), pushes them over an RFC destination of Type G to the Smart Gateway, and streams them to Apache Kafka, Confluent Cloud, Databricks, Snowflake, IBM watsonx.data, and other targets, with topics and Schema Registry entries created automatically and schema evolution supported.
Onibex ASK (Agentic Semantic Knowledge) provides a semantic layer for querying SAP data through natural language agents. Source code for OneConnect is available at the oneconnect-docs GitHub repository. Learn more at onibex.com.